

This document provides a high-level architecture to build a borderless open data lakehouse that establishes a highly governed, secure pipeline from raw borderless silos directly to AI-driven actions. It shows how to unify fragmented enterprise data across Google Cloud, other cloud providers, and live operational databases without relying on fragile extract, transform, and load (ETL) pipelines that can duplicate data.
The intended audience for this document includes data engineers, data architects, and AI developers who need to design performant federated systems that use open standards. The intended audience might also navigate enterprise constraints, such as borderless network routing and strict identity and access management isolation.
The deployment section of this document provides a code sample that helps you build and deploy the architecture that is described in this document.
Architecture
The following diagram shows a borderless architecture with a central lakehouse in Google Cloud.
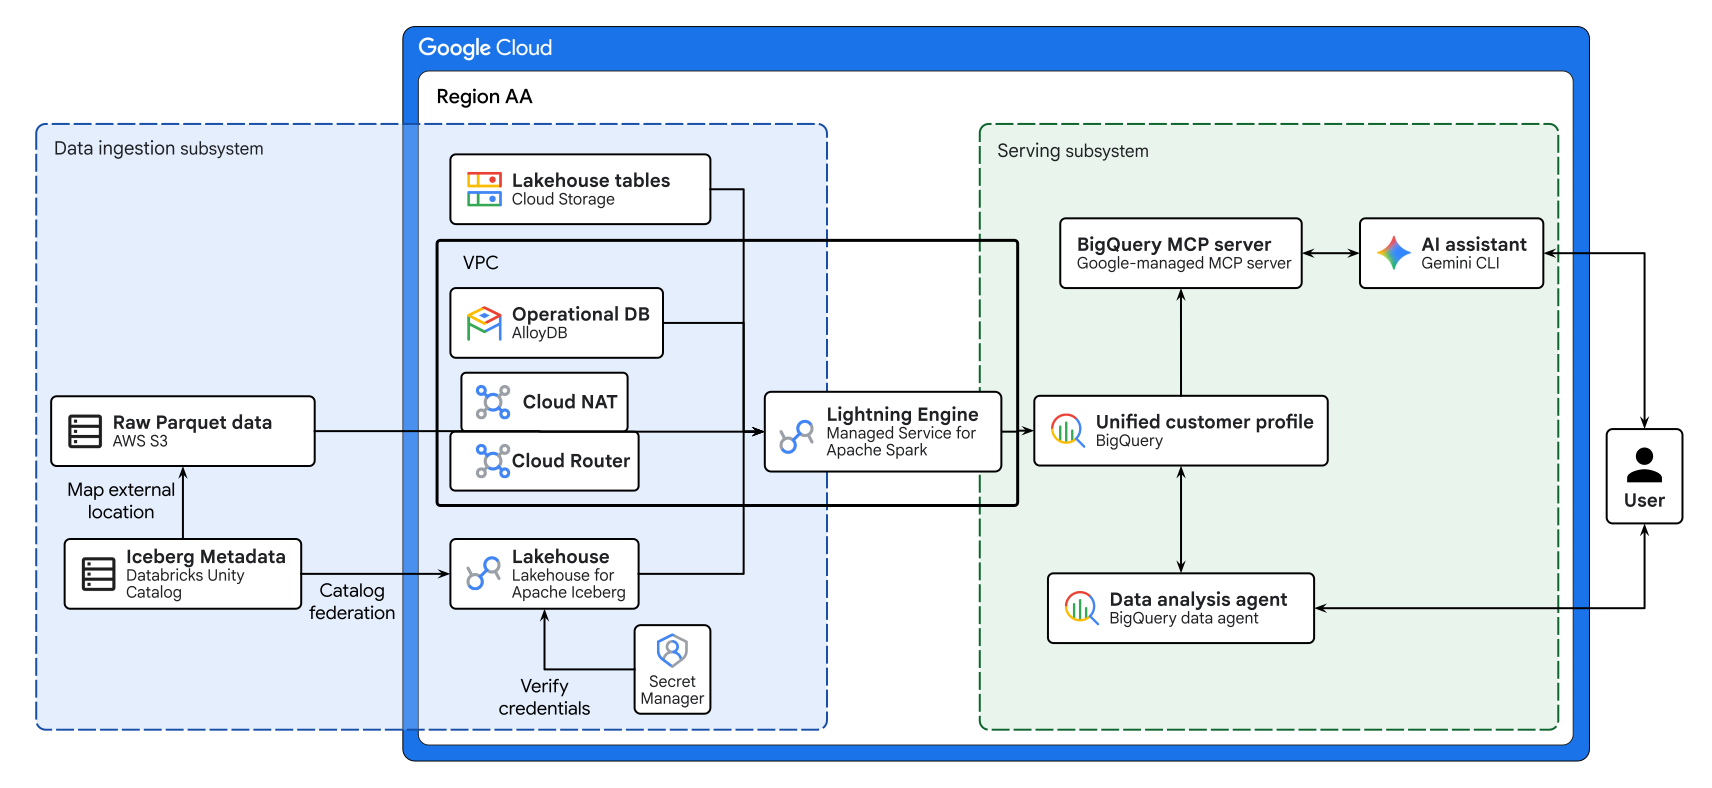
The architecture in the preceding diagram consists of two subsystems: data ingestion and serving.
- The data ingestion subsystem ingests data from external sources. It uses a central lakehouse to unify and process fragmented databases into a unified customer profile in Google Cloud.
- The serving subsystem lets users query an AI assistant and a data analysis agent to analyze the consolidated data.
The following sections describe the components across the subsystems.
Data ingestion subsystem
The data ingestion subsystem contains the following components:
- Managed Service for Apache Spark with Lightning Engine
-
A service that provides a distributed processing engine that handles complex analytical workloads, such as large-scale, borderless data joins and transformations. To maximize compute efficiency, Managed Service for Apache Spark uses Lightning Engine to handle the massive multi-way joins, complex windowing, and behavioral aggregations that are needed to combine the borderless data sources.
Managed Service for Apache Spark uses Lightning Engine to execute the distributed join by ingesting data from the following paths:
- Parquet files from Amazon S3.
- Cloud Storage event logs.
- Live transactional data from AlloyDB for PostgreSQL through BigQuery connections .
- External data sources
-
The enterprise data assets that reside in other cloud environments. In the architecture that this document describes, the external data sources are the following:
- Databricks Unity Catalog: An external catalog that manages metadata for open-format Apache Iceberg tables.
- Amazon S3: An external object storage service that stores the raw data files for the Iceberg tables in Apache Parquet format.
Connecting to external data sources lets you analyze data in place and avoids the need for costly and time-consuming data migration. Although this example architecture uses Databricks Unity Catalog and Amazon S3 buckets, you can use this architecture pattern with other external Iceberg catalog services and cloud storage providers.
- AlloyDB
- A high-performance database for hybrid transactional and analytical processing (HTAP), such as when you manage real-time inventory or live customer profiles. The BigQuery AlloyDB federation enables analytical engines to send a query from BigQuery directly to the live transactional data that is stored in AlloyDB. This approach helps to avoid the latency and overhead that are associated with change data capture (CDC) pipelines.
- Cloud Storage
- A scalable object storage service for high-throughput data, such as clickstream events. To help ensure that the data can be accessed by a variety of processing engines, use Cloud Storage to decouple the data from specific compute services and store the data in the open Apache Iceberg format, such as Apache Parquet.
- Borderless Lakehouse
-
The central metadata and governance system that enables a unified borderless federation. To establish connection to the lakehouse metadata, Lakehouse performs the following actions:
- Connect to Databricks Unity Catalog to resolve the schema and routing information for borderless data.
- Send a request to Secret Manager to verify credentials:
- If credentials are approved, establish direct connection to lakehouse metadata.
- If credentials are denied, return an error message and abort the operation.
- Cloud NAT and Cloud Router
- Managed services that enable resources within the Google Cloud network to securely access the data from external cloud sources without exposing those resources to the public internet.
- Virtual Private Cloud (VPC)
- A service that provides a private, secure, isolated network for all of the Google Cloud resources that are deployed as part of this architecture.
- Secret Manager
- A service that securely stores the Databricks service principal credentials, such as client ID and secret, for borderless authentication.
Serving subsystem
The serving subsystem contains the following components:
- Unified customer profile
- A BigQuery database that consolidates the output of distributed Spark jobs. The BigQuery table transforms fragmented borderless metrics into complex denormalized data types and serves as the central, governed datastore for analysis.
- BigQuery data agent
- A conversational analytics agent that lets users query data directly in BigQuery and generates enterprise insights. The agent enforces security and governance guardrails on the queries.
- BigQuery MCP server
- A Google-managed Model Context Protocol (MCP) server that provides access to BigQuery data. The BigQuery MCP server securely exposes the governed lakehouse context to local or external AI models, like Gemini CLI. It enables end-to-end agentic workflows without requiring AI engineers to build and maintain custom REST API middleware.
- Gemini CLI
- A command-line AI assistant that lets users interact with the unified customer profile to generate personalized, data-driven content, such as personalized marketing campaigns. The Gemini CLI acts as a client for the BigQuery MCP server to access the data that is stored in the unified customer profile.
Products used
This example architecture uses the following Google Cloud products and tools:
- Lakehouse: A high-performance storage engine that lets you build open data lakehouses and provides a unified interface for advanced analytics and AI.
- BigQuery: An enterprise data warehouse that helps you manage and analyze your data with built-in features like machine learning, geospatial analysis, and business intelligence.
- AlloyDB for PostgreSQL: A fully managed, PostgreSQL-compatible database service that's designed for your most demanding workloads, including hybrid transactional and analytical processing.
- Managed Service for Apache Spark: A managed service that runs Apache Spark batch workloads on a managed compute infrastructure.
- Cloud Storage: A low-cost, no-limit object store for diverse data types. Data can be accessed from within and outside Google Cloud, and it's replicated across locations for redundancy.
- Gemini: A family of multimodal AI models developed by Google.
- Google Cloud MCP servers: Google-managed remote services that implement the Model Context Protocol (MCP) to provide AI applications access to Google and Google Cloud products and services.
- Cloud NAT: A service that provides Google Cloud-managed high-performance network address translation.
- Cloud Router: A distributed and fully managed offering that provides Border Gateway Protocol (BGP) speaker and responder capabilities. Cloud Router works with Cloud Interconnect, Cloud VPN, and Router appliances to create dynamic routes in VPC networks based on BGP-received and custom learned routes.
- Virtual Private Cloud (VPC): A virtual system that provides global, scalable networking functionality for your Google Cloud workloads. VPC includes VPC Network Peering, Private Service Connect, private services access, and Shared VPC.
This example architecture uses the following third-party products:
- Databricks Unity Catalog: A unified governance and metadata catalog for data and AI assets on the Databricks platform.
- Amazon S3: A storage service from Amazon Web Services (AWS) that stores and manages data as objects.
Use cases
This reference architecture is designed for organizations that need to unify siloed data from multiple cloud environments and on-premises systems to drive analytics and AI initiatives. This architecture provides the following benefits:
- A borderless unified profile: A single, holistic view of business entities that lets analysts and decision-makers gain comprehensive insights. This unified view improves accuracy of analytics and it helps ensure that data is consistent and up-to-date regardless of where it's stored.
- Reduced operational complexity and lower total cost of ownership (TCO): Lakehouse helps to avoid the need to build and maintain brittle data pipelines. This approach lets you query data directly where it resides across different clouds. It avoids the operational overhead, storage costs, and latency that are associated with physical data movement.
- Agentic AI workflows: AI agents empower data analysts to translate complex behavioral aggregations directly into actionable business strategies. Agents let analysts securely access the structured, governed lakehouse data through standard protocols.
The following are examples of use cases for the architecture that's described in this document:
- Real-time retail analytics: A retail company needs to make immediate decisions based on sales and inventory. This architecture lets them combine their static product catalog data, which is managed in AWS, with live sales transaction data from their operational AlloyDB database on Google Cloud. Analysts and store managers can query this unified view at predefined batch intervals to monitor the performance of a sale, identify fast-selling items for restocking, or analyze regional buying patterns as they emerge.
- Customer personalization: A financial services firm wants to provide its relationship managers with a complete and unified view of their clients. The firm can use this architecture to unify historical marketing engagement data from a data lake on AWS with live customer account information from AlloyDB. A relationship manager can then use the AI assistant to ask questions, such as "summarize the last three transactions for this client and draft a personalized email that suggests a new high-yield savings account."
Design considerations
This section describes design factors, best practices, and recommendations to consider when you use this reference architecture to develop a topology that meets your specific requirements for security and cost.
The guidance in this section isn't exhaustive. For more information about design factors and best practices, and for recommendations about building and deploying a multi-agent AI system, see Multi-agent AI system in Google Cloud.
Security, privacy, and compliance
To help enforce the principle of least privilege, manage access through system-managed identities. Consider the following recommendations:
- To create and manage permissions for Google Cloud resources, use Google's Identity and Access Management (IAM) service.
- To securely access raw data in Cloud Storage, use BigQuery Cloud resource connections.
- To securely authenticate cross-cloud Databricks connections, use Lakehouse catalog federation with Secret Manager.
Agent security and governance
To help address the unique security risks of AI agents, Google recommends an approach that combines deterministic security controls with dynamic, reasoning-based defenses:
- Human oversight: Incorporate a human-in-the-loop flow in business-critical systems so human supervisors can review outputs and approve, override, or pause agent actions.
- Agent Identity: Assign each agent a workload-bound identity to enforce least-privilege access control and centrally manage credentials for external tools.
- Agent Gateway: Enforce ingress and egress traffic governance, default-deny access policies, and inline prompt and tool inspection with Model Armor.
- Agent Registry: Verify that agents only connect to approved subagents and MCP tools.
Cost and performance optimization
To help ensure that your agent configurations meet your cost and performance requirements, consider the following recommendations:
- Compute selection: To optimize performance and cost, select a compute service that is best suited for each part of your workload. A modern data lakehouse doesn't rely on a monolithic compute service. To perform exact-match filters to operational databases, use BigQuery federated queries. To offload memory-heavy and complex data manipulation, such as vectorized borderless joins, use Managed Service for Apache Spark with Lightning Engine.
- AI model grounding: To mitigate AI model hallucinations, ground your model on the unified customer profile to enforce business definitions and statistical validation. When you expose the AI model to raw, unaggregated borderless data across billions of rows, it can lead to excessive token consumption and high hallucination rates.
- Network topology and egress strategy: To help ensure reliable performance and minimize data transfer costs over borderless networks, use Cross-Cloud Interconnect to establish a private connection between Google Cloud and AWS. Otherwise, data query over public internet from Google Cloud to AWS can incur high egress fees and unpredictable latency.
Deployment
To deploy this architecture, see Building a borderless open data lakehouse Codelab. This sample implementation helps you provision the specific network infrastructure, execute C++ PySpark workflows, and configure AI agents to safely interact with your lakehouse.
What's next
- Learn how to use the Lakehouse runtime catalog with tables in BigQuery.
- Learn how to accelerate Spark with Lightning Engine.
- Learn how to analyze data with conversations.
- For an overview of architectural principles and recommendations that are specific to AI and ML workloads in Google Cloud, see the AI and ML perspective in the Well-Architected Framework.
- For more reference architectures, diagrams, and best practices, explore the Cloud Architecture Center.
Contributors
Author: Hyunuk Lim | Developer Advocate
Other contributors:
- Brad Miro | Senior Developer Advocate
- Samantha He | Technical Writer